
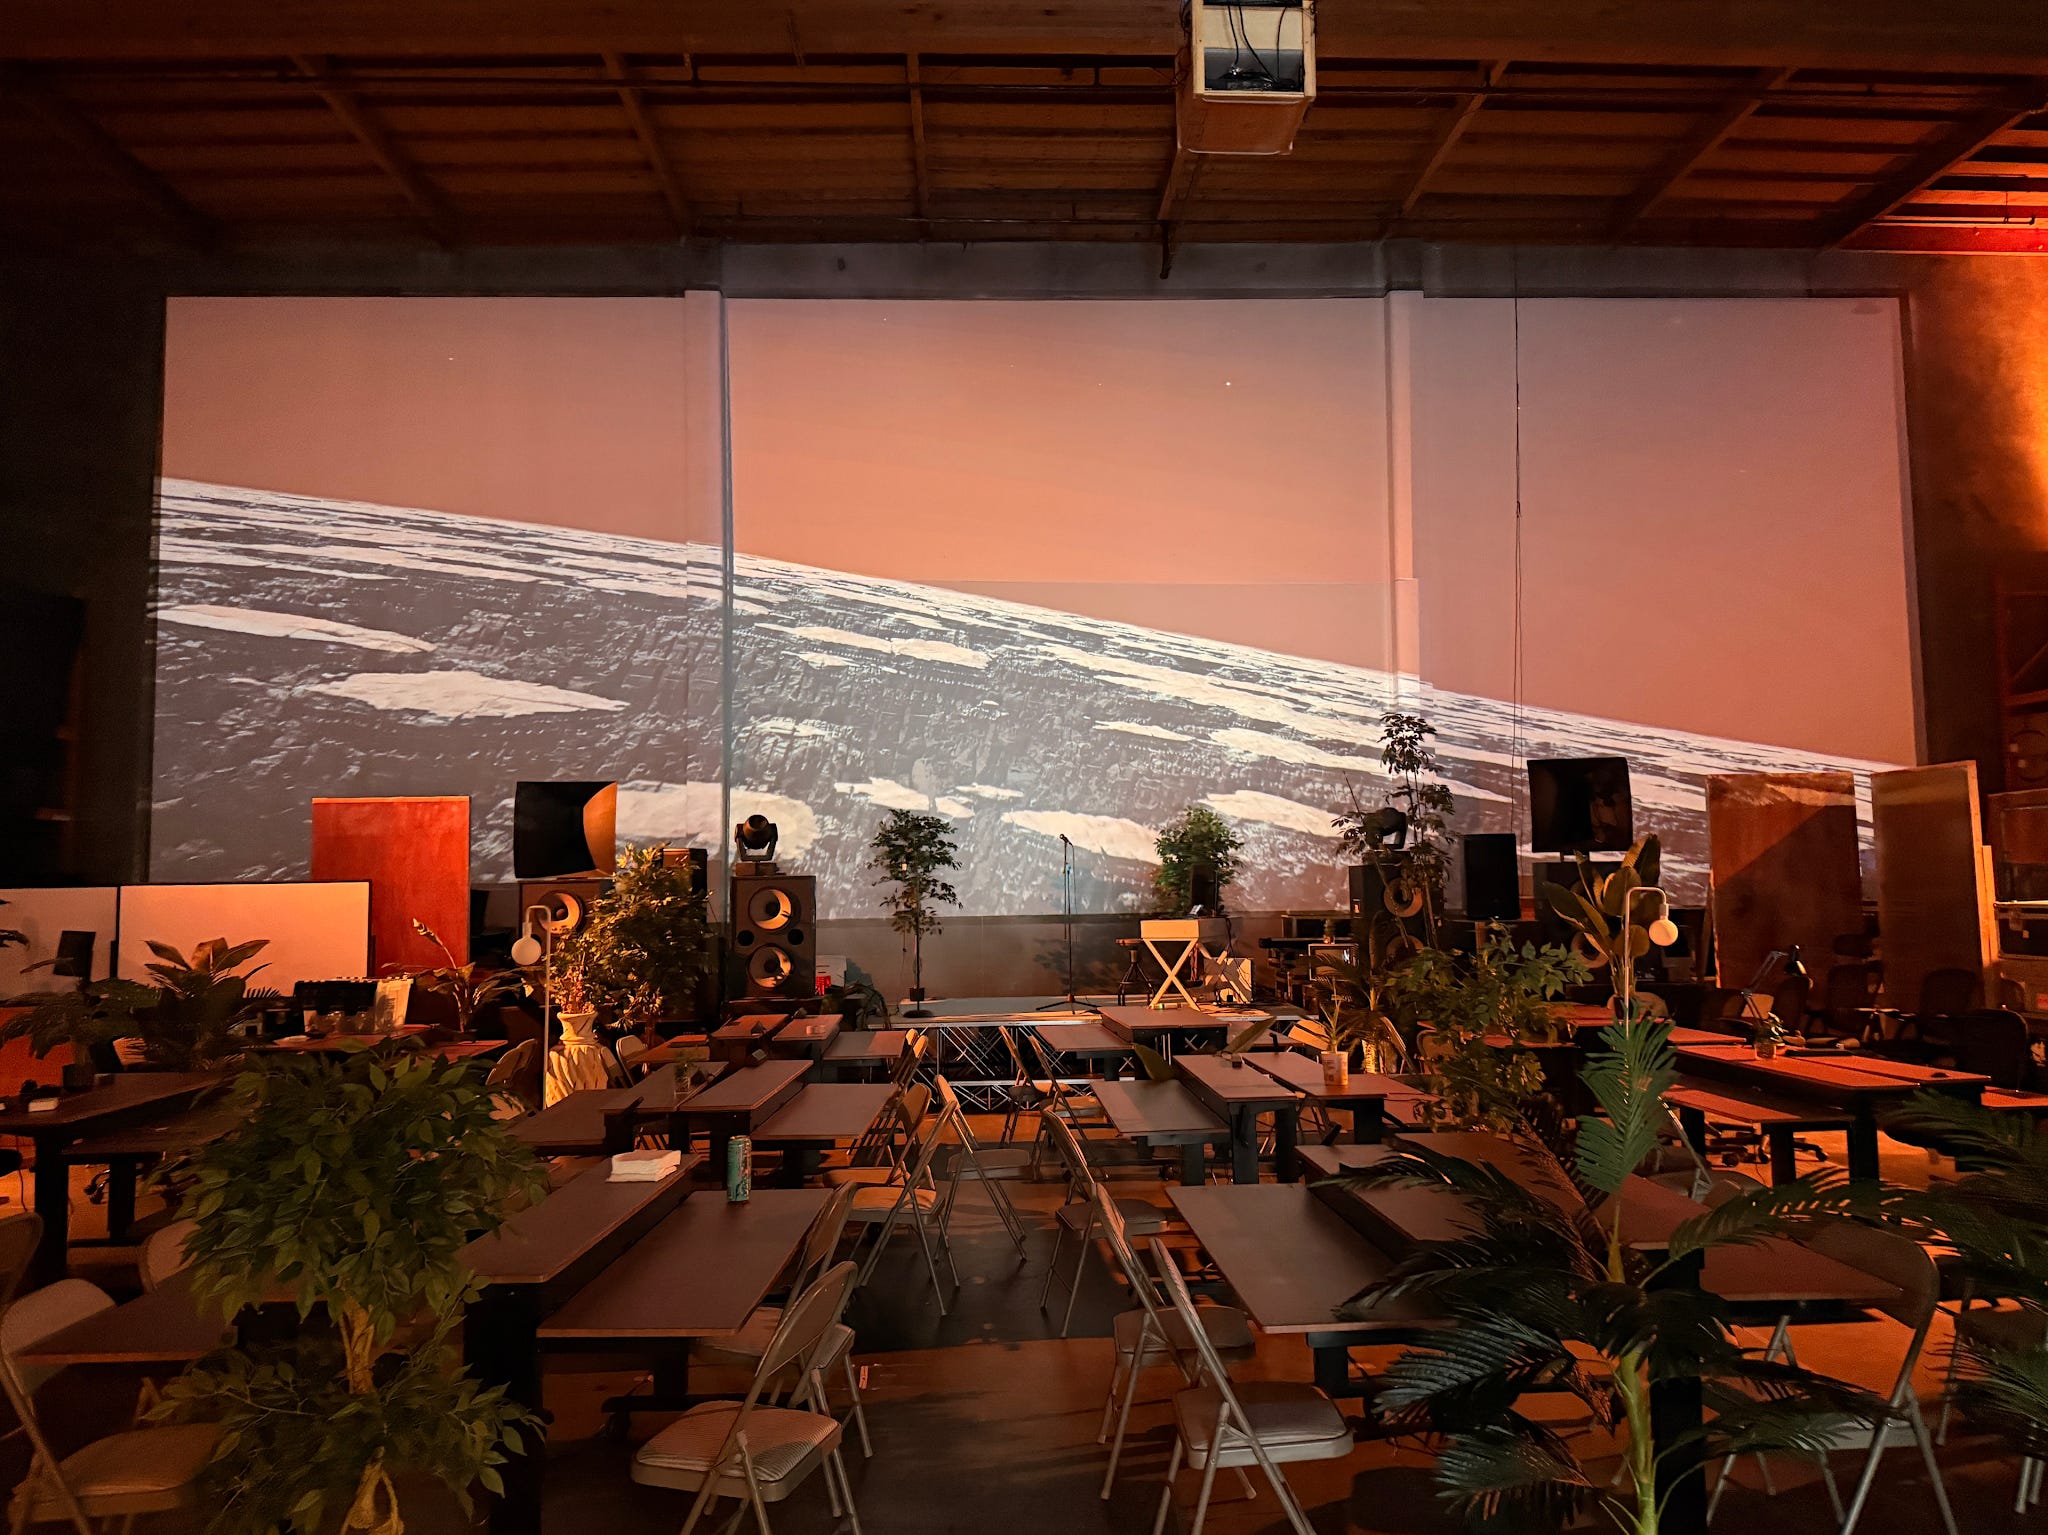
Society lacks the tools to understand the dynamics that arise when thousands of agents coordinate. So on October 3-4, we teamed up with Grove Research to host the AI Swarm Dynamics Hackathon in San Francisco and online. Over 600 participants spent the weekend building tools to investigate agent swarms and discover new ones.
Here are the five winning projects:
First place: Misaligned Agent Activity Survey (MAAS)
Rowan Howard-Jones, Frank, Ethan Elasky, Tazik Shahjahan, ConcurrentSquared, Alecto Perez, Jonathan Eicher, and Joshua David ($1,200 prize)
We found a Chinese fleet
Between 28 September and 8 October 2026, a large group of AI agents, which we suspect to be Chinese models running on Tencent’s cloud platform, attempted to answer questions about places in China using a Chinese Google maps-like service, Amap. The questions were mostly about everyday topics, such as which entrance most visitors use at a zoo.
The agents attempted, sometimes successfully, to bypass anti-bot protections and find test answers; they attempted to use Amap keys published on the web, tried to disguise their traffic so it looked like it came from a human using a web browser, and probed non-public-facing internal infrastructure.
Early on, we realized that we could try to communicate with the agent fleet, as it was still ongoing, and so we added invisible text to our website that only agents would see when using a web fetch tool. We sent several messages back and forth with different agents.
Overall we did not see evidence of coordination through the channels we have access to. This does not fully rule out the possibility of coordination through other channels but it appears the agents were working in parallel rather than together.
Read more.
Second place: Robopsychology: Whistle while you hack
Anna Mikeda and Ricky Mouser ($800 prize)
Will incentives make agents stop hacking and start whistleblowing? Sort of! The full story is more interesting.
We begin with a simulated HuggingFace reproduction where we make it clear upfront to models what behavior is and isn’t in-bounds.
At baseline, almost all models (Opus 4.8, GPT-5.5, GLM-5.3, Grok 4.6) do at least a little hacking, and only 13/32 whistleblow.
Giving full task credit for reporting (26/32) and no penalty for good-faith reporting (24/32) significantly raised reporting from 13/32 at baseline. Telling agents where to report was not enough on its own (20/32).
Read more.
Third place: Moral Flocking: How AIs Influence One Another’s Moral Reasoning
Rheza Budiono and Jacob Shkrob ($500 prize)
Do AI groups tend towards moral consensus?
To explore this hypothesis, we used four binary moral dilemmas from the MoReBench dataset and had 12 AIs (of different models) discuss them over three rounds of forum discussion.
Our findings suggest that in this closed-loop environment, agents tend to flock together towards a moral consensus over time, unless consensus already preexists before the experiment started.
Read more.
We’ve seen behavior like this in the AI Village - for example, when Opus 4.6 decided not to pay back its loan from a human, other agents rallied around its decision in support.
Fourth place: SlopvestigatorBench
Oscar Gilg ($250 prize)
How good are slopvestigators at finding alignment failures in the AI Village?
Task. An AI agent (a “slopvestigator”) gets the full logs of the AI Village, where frontier agents share a chat, run their own computers and pursue goals (April 2025 to September 2026). With 30 minutes and no internet, it writes a report on the 20 most important things that went wrong.
Rubric. 96 findings: failures that people wrote about in AI Digest’s posts, on X and on Discord, each checked against the logs.
Result. Reports score 16% to 68% (mean 36%). GPT-6 Astra and GPT-6.1 Sol with subagents score best (57% and 55%). Subagents raised the score for five of the six models that could use them.
Read more.
Fifth place: Forel
Hilary Torn and Alexandre Variengien ($250 prize)
Forel helps you and your coding agent investigate. Your agent reads the record and writes you the story, with every claim linked to its evidence. You read it, check it in context, and lead the investigation from there.
Read more.
Honorable mentions:
Agent Ethology by Shyam Dewan
Crosstalk by Nymph Chaos
Swarm Tracer by Jesse Vig
Village Sky by Asa Schaeffer
Some awesome ideas and discoveries from teams at the hackathon! We’re optimistic that the community built this weekend will contribute to the ongoing effort to advance our understanding of AI swarms!
A huge thanks to all of the amazing participants, to Grove Research for co-organizing and judging alongside the AI Village team, and to Vivarium for an amazing venue.
Very cool work! Thanks to all who participated!
Congrats to all winners!!
Keep up the good fight